

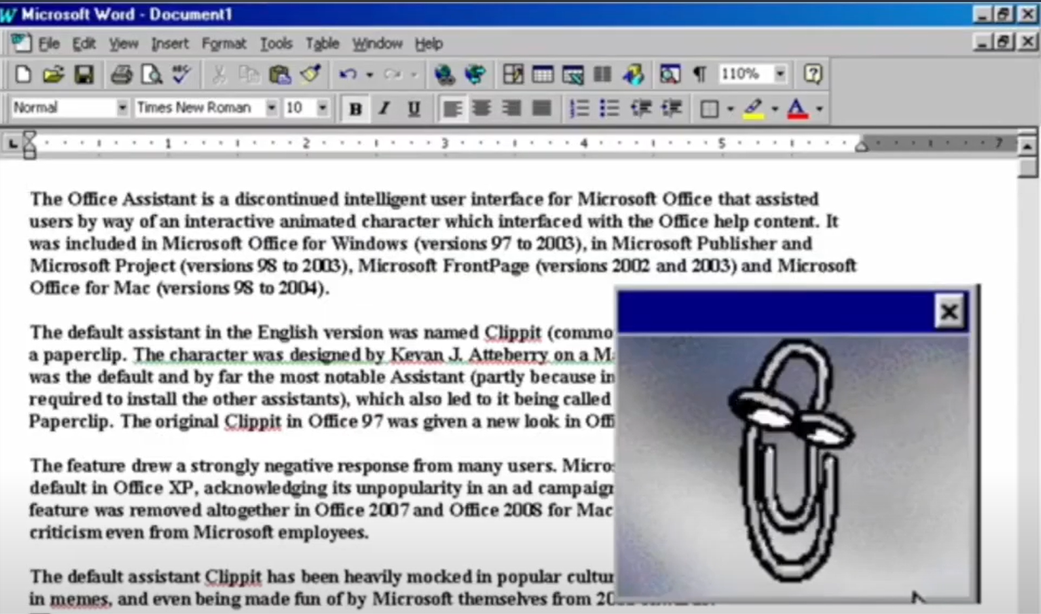
A primitive “virtual assistant” named “Clippy” (Microsoft) released in 1997 that evolved to more sophisticated chatbots such as “Cortana” and “Copilot”.
AI has been used in scientific research for decades.
When I came of age as an aspiring engineer and data scientist, chatbots were fairly primitive with very limited capabilities or specific uses. “Virtual assistants” in programs like Word (Clippy, Cortana which evolved to ‘Copilot”) or Apple products (Siri) were used to make these programs more user-friendly and appealing but generally had very limited capabilities. Their voices were also still somewhat “robotic” and users complained about some of its limited speech recognition capabilities. They also couldn’t “learn” as evidenced by their inability to understand follow-up questions. They used speech recognition (which is non-generative AI), and couldn’t process raw “conversational language” nearly to the capabilities of current chatbots. However, by the mid-to-late 2010s, there were a lot of promising technological developments in AI technology and which were integrated into these programs.
Humorous cartoon about the evolution of Virtual Assistants in Microsoft Word. “Clippy” was relatively unpopular and disliked by Microsoft users.
AI, however, very much existed and was used by many academic researchers as a tool to analyze their datasets. The advent of large datasets, particularly in the area of microbiomes, required far more advanced statistical and computational skills to identify patterns in the data. However, AI use was largely “non-generative”. This means that it does not really “generate” answers like it was “talking” to you. They relied heavily on sorting and classifying data and using pre-existing algorithms and models.
I do (and still do) something called “Supervised Machine Learning” on my own datasets. Machine Learning uses existing datasets to train a model and then predict outcomes. It’s more advanced than say, linear regression, because it can handle a lot of different variables and find relationships that would be difficult to trace manually. These algorithms are well-established and have been around for decades. In fact, Neural Networks were first used to solve “real world” problems in the 1950s. While this process can “generate” answers, they tend to be either numbers or binary yes/no answers, quite different than the rambling interpretations of a chatbot.
For example, I could measure the species and number of fish in several lakes over different seasons and regions. I then feed some of this data into my machine learning model (train the model) and test its accuracy in predicting the number and species of fish from predictors (seasons, regions) from the remaining dataset. I then compare the predictions to my collected data and obtain an accuracy score. If the score is too low, I can try another model type. Once the model is developed and has an appropriate accuracy score, I can then ask it to predict the species and number of fish in any lake.
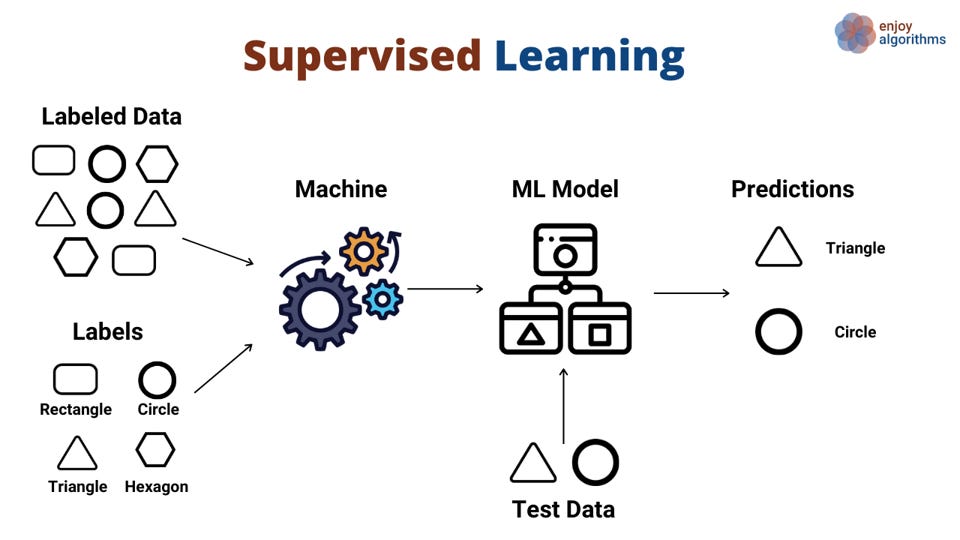
Supervised Machine Learning relies on “labelled” datasets and provides simplistic categorial predictions. This was and still is one of the most popular uses of AI in scientific research and is ubiquitous across almost all fields. This is “non-generative” AI.
This process involves coding and data cleaning (labelling, categorizing, standardizing data) in software platforms like R or Python. I build the code myself and it does not cost me anything. There is no “ethical issue” since I only run it on my local computer, feed in my own data I collected and carefully interpret my results. I perform extensive validation and testing of the dataset as well. I follow the principles and ethics of data science. As a result, I have made several interesting discoveries that were not previously known before. I am 100% confident that the science and recommendations I am making are valid. “Old-fashioned” AI for a win! These models do not have any other “AI” component other than developing a complex decision “tree”.
Platforms like ChatGPT do include Machine Learning but are much more complicated. They incorporate Natural Language Processing, large language models, and reinforcement learning based on human feedback. Data does not need to be labelled or categorized for analyzed. It can handle raw data formats and generate responses and handle follow-up questions from users. They can generate 2-way conversations with a user. Often, this is all “hidden” behind a friendly Graphical User Interface and would be impossible for an amateur coder to develop on their own.
Chat GPT interface. This is “generative” AI.
So, I could feed the fish dataset into an AI chatbot and ask it to predict species and number of fish. However, there is no way to validate that outcome, test different algorithms, or obtain an accuracy or reliability score. I have to go with whatever it says. I have no idea if it is training on data besides my data set. It’s murky where the data that ChatGPT is using to “train” itself is actually coming from and given numerous lawsuits emerging, it is likely using copyrighted text. A few days ago, it was revealed that Meta’s AI model uses pirated and unpublished work to train on. It can very well come from disreputable data sources, flawed data sets and poses serious concerns for misinformation or disinformation. Plus, the platform uses my answers and responses for other purposes. As a scientist, how can I confidently convey these results to the public?
AI chatbots could potentially be used to analyze a large data set in batches on a platform like Python. However, to do so, you often need something called an “API Key” to access the chatbot program through your code. This requires creating an account, and providing your email address, name, and possibly credit card information. Thus, you must be careful that your dataset does not contain sensitive information. The platform can also “hallucinate” or generate nonsensical answers just to provide an answer. Big Tech companies also have a poor record of data privacy.
So, I tested out an AI platform and then a conventional supervised machine learning on a publicly available dataset. I found that conventional supervised machine learning performed much better.
As a researcher, it’s also important to understand every step of your data analysis. I worry that AI platforms “hide” what’s going on behind the scenes so it’s hard to validate and train datasets. It’s hard to figure out what type of model they are using and how they train and validate their own model. Plus, they claim to be “open” to the public, but there are limits/quotas to how much you can use for “free” then they charge you! I’m not paying money to get subpar results.
If you are a scientist, researcher, or writer, be careful of AI use. You have an ethical responsibility to make sure anything you publish is 100% accurate.
Here are my recommendations for ethical/nonethical uses of AI in scientific/academic research.
Non-Ethical Uses of AI
Using AI to write text for publication. Using it to write or edit the text of your dissertation, homework, academic manuscript. This can constitute academic fraud or cheating in many classes. While some academic journals do allow AI written manuscripts as long as it is disclosed and cited, most literary journals will NOT accept anything AI generated.
Using AI to edit your work. Not only does AI train on copyrighted text, it will have access to your text which may contain sensitive information.
Feeding your carefully curated document with sensitive data into a Chatbot platform on your Internet browser.
Cutting jobs and replacing humans with AI.
Using AI to invade other people’s privacy or commit fraud.
Suggesting “prompt engineering” as a future profession. While developing good prompts and inclusion/exclusion criteria for data analysis and model development is a definite skill and might be valuable for a data scientist, it is not a career path. Yet educational platforms like The Chronicle of Higher Ed and AWP are touting this without providing any evidence of such careers or considering that such a career would be rendered obsolete quickly. Don’t bank your future on it, is all I’m saying.
More Ethical Uses of AI
Developing and coding your own AI model that is run on your local computer. If you are not a coder, many universities have coders and consultants who will create the code for you. Or using a specific, private, AI software program approved by your company/research group. If you build it yourself on open-source platforms like R or Python, it’s also free!
Developing rules and criteria for exclusion and inclusion of data in your model. Having well-labelled datasets.
Extensively validate and test and train your model before publishing your results.
Making your code and data publicly available on reputable databases and open-source platforms (keep sensitive data anonymous especially if using data sourced from humans).
Obtaining informed consent from research participants and inform them of how their data will be used.
Checking and correcting for bias in your AI model.
If you must use AI Platforms for research…
Import and run the chatbot platform through another software like Python; do not use the chatbot provided on the internet browser. Running it on your local computer can allow you do tailor and customize the coding of your program.
Build in code to detect AI hallucinations if using a chatbot. Customize the program as much as possible to eliminate bias on your end. Document your process and be transparent in your modeling process.
Keep sensitive data (names, addresses, emails, industry secrets) anonymous. Research ways to ensure privacy.
Fully disclose and cite the AI platform in your work. If you have to “hide” that you used it, then you should not have used it in the first place.
Ethically Grey Areas
Idea/content generation. Is this “cheating?”. Maybe not, but it is better to come up with “ideas” for research through searching literature, books, reports, and communication with professionals. Looking up “ideas” for research on chatbots is questionable especially if you have an advanced degree in your field.
Professional communications. An industry professional sent an email that the professor immediately noticed as written by ChatGPT since it sounded strange. They immediately questioned their credentials and the validity of their email. People may take you less seriously if you use AI bots to generate simple things even like emails. Again, you also don’t want to feed in sensitive information about your company/research into a chatbot either.
Writing computer code. For an experienced programmer who just needs to debug their code, maybe. However, you must fully understand the principles of the code, what each step means, and how to validate your work. Otherwise, it may not run as you intended.
Conclusion
Many people praise AI because it creates a fantasy of connection, relationships, mastership, efficiency, and ease. If you are a writer or scientist worth their salt, you will be skeptical and circumspect about the implications, limitations, and uses of AI Chatbots. Humans have created the most profound, beautiful innovations and art works. Be proud to be a human!!
It just makes me grateful that I finished my PhD just before AI really took over. This should be a whole course taught to researchers so they are critical and careful about their AI use.
Thank you for talking about the ethics and gray areas. The company I work for has been pushing us to use AI as much as possible. Perhaps not surprisingly, we had a pretty large round of layoffs this week. The next day, there was a meeting with the whole department where leadership tried to convey sympathy. Much of what they said was clearly AI generated. It felt so disingenuous. I totally agree with your point about emails, instantly kills credibility.